

Introduction
Among the many resources provided by a forest stand, timber has been one of the most important throughout history. Volume calculation is a key aspect of forest management (Cordeiro et al., 2015); for each tree species, provenance, shape, size, and age, as well as biological and environmental factors determine the merchantable volume of forest stands (Paz-Pellat et al., 2021).
The choice of methodology for estimating the merchantable volume of a forest stand is a key aspect in terms of the resources required, both technical and human (Rojas-García et al., 2015). For example, there are estimation methods that require measurements on standing or felled trees. In the latter case, measuring certain variables, such as diameter at multiple heights, is clearly easier (De Barros et al., 2024). For standing trees, volume calculation using traditional volume equations and regression models involves statistically relating independent variables to one or more dependent variables (De Lima et al., 2021; Montgomery et al., 2021). Another estimation methodology is artificial neural networks (ANN). The main aspects to consider when classifying ANN. The main aspects to consider when classify ANN models are their topology and learning mechanism (Negro & Pons, 2022). Based on topology, ANN are classified according to how neurons are organized and arranged to formal layers. Fundamental parameters include the number of neurons per layer, the number of layers, the type of connections between neurons, and the degree of connectivity. From a topological perspective, networks are classified as either single-layer or multi-layer; the latter can be further distinguished into feedforward networks (connections only in one direction, without feedback loops) and feedforward/feedback networks (with forward and backward connections), in which Rumelhart et al. (1989) first defined the backpropagation learning algorithm.
ANN are applied in a wide range of areas, including financial management (Kaur et al., 2025), building construction (Liu et al., 2021), energy usage (Ashkan et al., 2023), water quality management (Afrifa et al., 2022), and industrial process modeling (Díaz-Martínez et al., 2023). Some examples of the usefulness of ANN in the agroforestry sector include the study of wildfires (Pérez-Sánchez et al. 2019), measurement of the physical properties of wood (Villasante et al., 2019), and estimation of water quality for food production (Carbajal-Hernández, 2017). Regarding tree species, there is extensive literature on eucalyptus and its clone (Cordeiro et al., 2015; Marques da Silva et al., 2014; De Barros et al., 2024; Tavares Junior et al., 2019). For conifer species, the work of Diamantopoulou and Özçelik (2012) is notable; they used ANN to relate height and diameter at breast height in Lebanon cedar and compared the prediction results with classical models. Similarly, Diamantopoulou and Milios (2010) modeled the volume of Pinus brutia Ten. specimens from reforestation using ANN.
Some studies focused on timber volume estimation evaluate the suitability of using ANN compared to other models. Amorim et al. (2021) compared ANN with two regression models to estimate the timber volume of Anadanta macrocarpa (Vell.) Brenan, Genipa americana L. and Mimosa casalpinifolia Benth. The ANN with two neurons in the hidden layer showed the best fit for all three species. Similarly, Fernández-Carrillo et al. (2022) compared four artificial intelligence (AI) models with two conventional models (Fang and Kozak) to estimate diameter at breast height of Tectona grandis L. f. as the dependent variable for volume. In this case, although the Kozak model showed the best results, all four AI models outperformed the Fang model. Additionally, it is important to consider whether the application of ANN models tends to overestimate or underestimate actual measurements, as this has commercial implications. Guzmán-Santiago et al. (2020) reviewed several tropical timber volume estimation studies and concluded that ANN tend to overestimate volumes. Similarly, Carratù et al. (2019) reported that volume estimates of timber bundles using ANN were overestimated by 1 and 2 %. In contrast, Moreno-Arteaga et al. (2019) concluded that volume estimation using ANN with satellite imagery neither overestimated nor underestimated timber volume predictions
Regarding Pinus sylvestris L., Villasante et al. (2019) use ANN to estimate parameters related to wood density. Similarly, Seki (2023) compared traditional methods with ANN to estimate the stem volume in this species. The use of ANN for the volume estimation (volume measurements) of Scots pine has been addressed by only a limited number of studies, although it is one of the species widely distributed throughout the world (Berendt et al., 2023). Furthermore, its wood holds significant cultural and commercial importance in many European countries (Houston Durrant et al., 2016; Kozakiewicz et al., 2020).
The objective of the present study was to compare six methodologies for estimating the merchantable wood volume of P. sylvestris: two radial basis function ANN with different input variables and numbers of clusters, two multiple linear regression models using two and three variables, and two traditional volume estimation formulas: Algan and Shumacher and Hall. The aim was to determine whether statistically significant differences exist among these methodologies in estimating the merchantable volume of P. sylvestris, and thus to draw conclusions regarding which methods are the most suitable for this species.
Materials and Methods
Study area
The study was carried out in 2023 using P. sylvestris specimens from the province of Segovia (Spain), specifically in the Navafría pine forest, located within the Sierra de Guadarrama National Park. This species holds great importance in Spain; according to the Forest Statistics Yearbook (Ministerio para la Transición Ecológica y el Reto Demográfico [MITECO], 2022), in 2021 a total of 1 398.22 m3 (with bark) was harvested, making it the third most logged conifer species after Pinus radiata D. Don and Pinus pinaster Ait. The primary use of this wood for sawmilling, with a roadside price of 51.6 EUR·m3. The species is notable for its high-quality wood and considerable economic importance, largely due to its low ecological requirements (Gallo et al., 2020).
Data collection
Based on plot information from the 1988 forest management plan review (García-López, 1995), a sample of 83 type trees was considered (a representative tree for each diameter class corresponding to a given species and site quality). For these trees, data were obtained on age, diameter at breast height (DBH, cm), total height (TH, m) and volume with bark (V, m3) estimated using Huber’s formula (Đuka et al., 2023).
In the field, once the trees were felled, measurements were taken starting at a height of 30 cm above the ground. Logs 1 m in length were cut up to a height of 10 m, and 2 m logs were cut from 10 m to the top of the stem. Volumes were measured from the 30 cm point corresponding to the beginning of the first log up to the minimum top-end diameter (7 cm). Diameters and log lengths were obtained using calipers. The ages of the specimens were estimated by counting growth rings. Maximum, minimum, mean, and standard deviation values of these variables for 83 specimens are shown in Table 1.
Table 1.
| Variable | Maximum | Minimum | Mean | SD |
|---|---|---|---|---|
| Age (years) | 116 | 37 | 78.05 | 19.14 |
| DBH (cm) | 67.3 | 19.5 | 34.35 | 9.63 |
| Total height (m) | 24.7 | 10.4 | 16.92 | 3.83 |
| Volume (m3) | 3.154 | 0.17 | 0.82 | 0.60 |
Models used
Given the small size of the training dataset, a radial basis function neural network was chosen for data analysis. This type of network shows rapid convergence and addresses the global problem by dividing it into smaller, local problems. It is a hybrid learning network with a multilayer feedforward architecture, consisting of an input layer, a hidden layer, and an output layer (López Sosa & Pérez Pacheco, 2017). The estimation of wood volume using the radial basis function neural network was carried out using two approaches, combining criteria of sensitivity, error, and computational cost:
ANN1: Radial Basis Function (RBF) Neural Networks with 12 clusters (groupings of the input space data) and three independent variables (input neurons): age, DBH, and total height.
ANN2: Radial Basis Function (RBF) Neural Network with four clusters and two independent variables or input neurons (DBH and H).
The decision to use one neural network with three input variables and twelve clusters, and another with two variables and four clusters, was made after training several configurations and verifying that these designs yielded the best results. Both approaches were compared with four conventional models: two multiple linear regression (MLR) models and the volume estimation formulas of Schumacher and Hall (1933, S&H) and Algan (1901). The characteristics of the models are summarized in Table 2.
Table 2.
| Model | Independent variables | Formula |
|---|---|---|
| MLR1 | Age, DBH and H |
|
| MLR2 | DBH and H |
|
| S&H | DBH and H |
|
| Algan | DBH and H |
|
V = tree volume,
Statistical analysis
The results obtained include the formulas of the multiple linear regressions, as well as the p-values for each of the coefficients of the linear models. In the S&H model, the estimation of β
0
use the estimator
It was verified whether the model residuals satisfied the assumptions of independence (Durbin-Watson test), homoscedasticity (F-test), zero mean (t-test) and normal distribution (Kolmogorov-Smirnov test). Since these are multivariable models, they also had to meet the condition that the model coefficients were not correlated, as correlations greater than 0.5 indicate the presence of severe multicollinearity, that is, correlating among the predictor variables (Kamoske et al., 2021). A paired-sample t-test was performed between each method and the actual scaling (volume calculated according to Huber’s formula; Đuka et al., 2023), thereby obtaining the p-values for the null hypothesis that the mean of the differences was equal to zero.
The statistical indicators used were as follows: mean squared error (MSE), root mean squared error (RMSE) and its relative (RMSE%), coefficient of determination (R2), precision of the mean deviation (P, %), mean percentage deviation (MD, %), and relative bias (%). To compare the six volume estimation methods, the estimation errors expressed as percentage were aggregated using the formula proposed by Soares et al. (2011):
The neural network models were developed using TensorFlow (Google Brain Team, 2015). Statgraphics Centurion (Statgraphics Technologies, Inc., 2024) were used to compute multiple regression models, whereas Excel was used to derive
Results
Estimates
The estimated coefficient values, along with the p-values from the t-test, were calculated for the MLR and S&H models. The results are shown in Table 3. A similar weighting of the variables DBH and TH is observed in both linear models. In the case of MLR1, since the variable Age shows a p-value greater than 0.05, the model can be simplified by excluding it, whereas in MLR2 and S&H, none of the variables can be omitted. Both MLR models meet the model assumptions regarding residual errors and coefficient correlations. The S&H model, although it satisfies the multivariable regression assumptions for residuals, shows an estimated correlation of 0.51.
Table 3.
| Coefficients (β1) | MLR1 | MLR2 | S&H | |||
|---|---|---|---|---|---|---|
| Estimate |
|
Estimate |
|
Estimate |
|
|
| Constant (β0) | -1.6105 | 0.00 | -1.6473 | 0.00 | -9.8671 | 0.00 |
| DBH (β1) | 0.0473 | 0.00 | 0.0462 | 0.00 | 1.7749 | 0.00 |
| H(β2) | 0.0522 | 0.00 | 0.0519 | 0.00 | 1.1538 | 0.00 |
| Age (β3) | -0.0010 | 0.42 | - | - | - | - |
Goodness of fit
Table 4 shows the values of the selected statistics used to assess the goodness of fit (MSE, RMSE, and R2), and the p-values from the paired-sampled t-test between each method and the actual volume measurements (according to Huber’s formula). It can be observed that the MSE values remain under 3 % for all models. The lowest MSE and RMSE values are found in the ANN models, whereas the highest values for both statistics occur in the three-variable linear model (MLR1). The R2 values indicate that the models explain between 91 % and 98 % of the variability in volume. The highest R2 values are observed in the NN1 model (R2 = 0.97) and in S&H (R2 = 0.97), while the lowest value corresponds to the MLR models (R2 = 0.91). In the test for equality between the estimated and actual values (paired sample mean difference test), the null hypothesis that the estimates equal the measured values cannot be rejected, even at a 90 % confidence level (p > 0.1). In this case, MLR models showed the best fit between the estimated and measured data, with p-values close to 1, indicating no statistically significant differences between the estimated and actual volume. In contrast, the Algan model presented the poorest fit (p = 0.1165).
Table 4.
| Model | MSE | RMSE | R2 |
|
|---|---|---|---|---|
| ANN1 | 0.003 | 0.057 | 0.974 | 0.966 |
| ANN2 | 0.004 | 0.063 | 0.968 | 0.983 |
| MLR1 | 0.030 | 0.174 | 0.915 | 0.999 |
| MLR2 | 0.017 | 0.133 | 0.914 | 0.999 |
| Algan | 0.015 | 0.122 | 0.959 | 0.116 |
| S&H | 0.006 | 0.082 | 0.972 | 0.606 |
Error calculation
The statistical analysis did not allow for a clear identification of the model that best estimated wood volume. Therefore, percentage errors and their total sums were calculated, as shown in Table 5. The lowest total estimation error was obtained with the ANN models, followed by the Schumacher and Hall (S&H) model. In contrast, MLR models accumulated the highest total errors among all models.
Table 5.
| Model | MD (%) | Bias (%) | P (%) | 100(1-R) (%) | RMSE (%) | Total (%) |
|---|---|---|---|---|---|---|
| ANN1 | 8.20 | 0.04 | 1.90 | 1.62 | 13.03 | 24.78 |
| ANN2 | 8.78 | 0.02 | 1.91 | 1.32 | 11.76 | 23.79 |
| MLR1 | 23.19 | 0.06 | 6.60 | 4.35 | 21.21 | 55.41 |
| MLR2 | 23.26 | 0.00 | 6.66 | 4.31 | 21.12 | 55.35 |
| Algan | 9.91 | 2.57 | 2.24 | 2.04 | 14.92 | 31.68 |
| S&H | 8.29 | 1.90 | 1.89 | 1.54 | 12.76 | 26.38 |
Mean deviation (DM), square root of the coefficient of determination (R), root mean squared error (RMSE) and mean deviation precision (P).
Comparison: estimated vs. actual volume
To observe the similarities and differences among the six methods studied, Figure 1 compares the estimated volume against the actual volume measured using Huber´s formula in 1:1 plots. MLR models produced similar results and showed the lowest slope values. ANN1 and ANN2 models yielded comparable results to each other, with steeper slopes than those of MLR models. The Algan and S&H formulas occupied an intermediate position. Using two or three input variables resulted in similar values for both the radial basis function ANN models and MLR models.
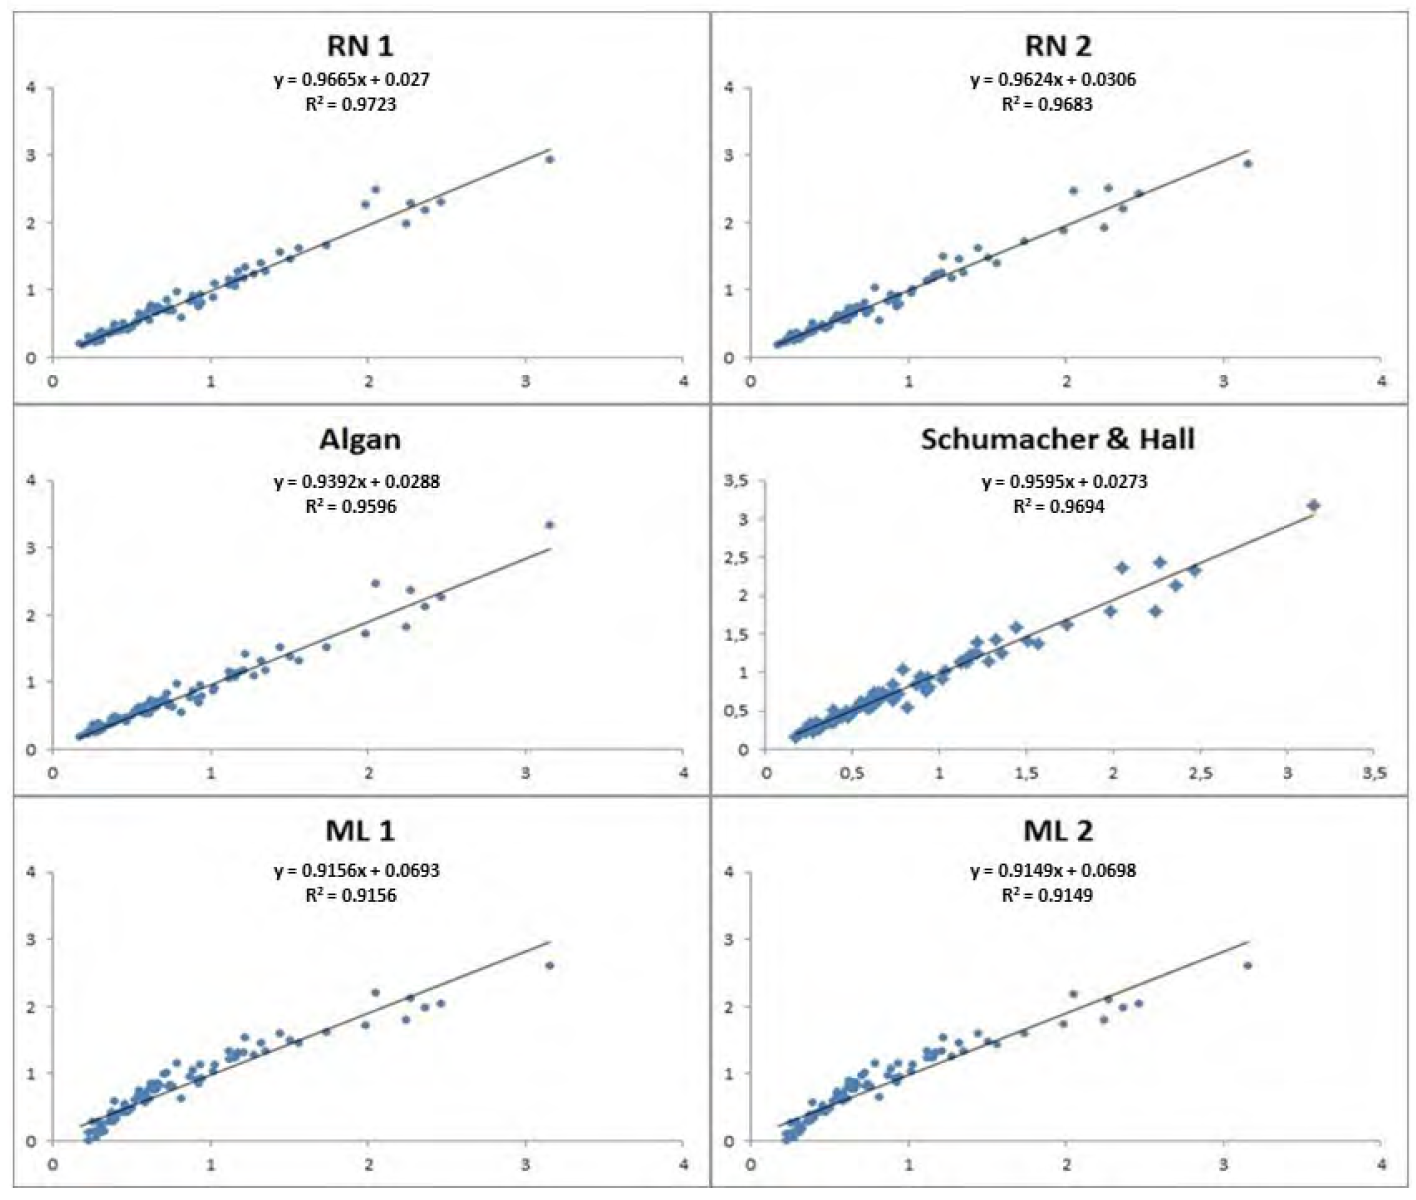
The average differences between the estimated and actual volumes are lower than 0.02 % for ANN2 and 0.04 % for NN1, with both models slightly underestimating the volume. In contrast, MLR models show no significant average differences (<10-6 %), whereas the Algan (-2.1 %) and S&H (-0.6 %) methods underestimate the mean volume of the 83 trees to a greater extent.
Discussion
For all models, RMSE values were below 0.18 and R2 values exceeded 0.91. A comparison of the results for Pinus brutia Ten. (Diamantopoulou & Milios, 2010), based on a similar number of individuals (63 specimens) as in the present study, indicates that the estimates obtained using ANN were slightly better for that species (RMSE = 0.028 and R2 = 0.99). All six methods produced linear adjustment with R2 > 0.9. Nevertheless, the two ANN yielded the lowest total sum of estimation errors and showed mean square error (MSE) values two to five times lower than those of the other models. When comparing the two ANN, ANN1 showed slightly lower error values than ANN2 for all measured error indices; however, these differences were approximately 1 %. Among the remaining methods, the S&H and Algan volume equation produced error estimates closest to those of the ANN, whereas MLR models showed the highest estimated error values.
The use of Algan’s formula for volume estimation does not appear in other studies that do include comparisons with Huber’s formula for eucalyptus (Souza et al., 2017). Huber’s formula is similar to Algan’s (using total height and mid-stem diameter as variables) but shows higher MSE values than those obtained with Algan’s formula applied in this study.
The S&H equation has been applied to eucalyptus stands in recent studies comparing volume estimates using ANN (Cordeiro et al., 2015; de Azevedo et al., 2020; Tavares Junior et al., 2019) and for volume measurement of stacked wood (De Barros et al., 2024). In all cases, ANN had better fits, although MLR proved to be efficient. In a study by Fernández-Carrillo et al. (2022), MLR produced the best results compared to four artificial intelligence models, including radial basis function ANN. In these studies, the R2 values obtained with the S&H formula were lower than those calculated for Scots pine volume estimation in Spain; nevertheless, this formulation achieved the best fitting results for the estimation of Mimosa caesalpinifolia Benth. Volume (Amorim et al., 2021) compared to NN. MLR and ANN were used in the work of Martínez-Blanco et al. (2012), showing similar results in terms of the error metric employed (MSE = 0.03).
The most used ANN models for volume measurement are the multilayer perception and the radial basis function network (Costa et al., 2022; Lotfi et al., 2024). Comparative studies of different ANN models for similar variables indicated that both types are suitable for these problems (Cordeiro et al., 2015; de Azevedo et al., 2020; Fernández-Carrillo et al., 2022; Seki, 2023; Tavares Junior et al., 2019). MSE and R2 values reported in all the aforementioned studies are of similar magnitude, which is also the case for the NN1 and NN2 models used in this research.
Total errors in volume estimation obtained using the ANN models and the conventional volume measurement formulas used in this study fall within the range reported by Soares et al. (2011), who found values between 17.5 % and 42.3 %. However, total errors calculated for the MLR models exceed this range by nearly 13 %. Except for the bias measure, MLR models show errors approximately twice those of NN fits and also fail to meet the model assumptions for residual errors, making their predictions unreliable. The S&H model shows a total error very close to that of the ANN models and, in its linearized form, satisfies the residual assumptions (zero mean, normality, independence, and homoscedasticity), which makes it a good predictive model. These results are consistent with the conclusions of Marques da Silva et al. (2009). Nevertheless, the S&H model shows an issue of dependency between the DBH and total height variables, which could lead to multicollinearity in the predictions. In addition, together with the Algan model, it exhibits the lowest probability of equality between predicted and measured volumes (p- values lower than 0.9).
It is difficult to compare the results with those of other studies, as no research using ANN-based methods for estimating the stem volume of Scots pine has been identified. The fitting results of the ANN models for P. sylvestris data in Spain are superior to those of the other models used for volume estimation. In both models (NN1, NN2), the total error is lower than 25 %, the proportion of variance explained by the models exceeds 95 %, MSE is below 1 % and the probability that the estimates match the actual values is greater than 0.9.
Stem volume can be estimated using multiple methods, and the choice of method is at the discretion of each expert (Guzmán-Santiago et al., 2020). In the case of Scots pine, the ANN1 and ANN2 models provide the best results and are very similar to each other, with the model using two neurons or input variables being preferable due to the principle of simplicity, or parsimony (Collazos et al., 2012).
In the review of other studies (Carratû et al., 2019; Guzmán-Santiago et al., 2020; Moreno-Arteaga et al., 2019), no significant differences were observed between the use of traditional or linear regression models and ANN models. This makes the application of ANN particularly useful, because they require fewer measurements and, therefore, can reduce costs (Marques da Silva et al., 2014).
Conclusions
A total of six methods for estimating the wood volume of Pinus sylvestris were compared. Estimation using artificial neural networks (ANN) proved effective for calculating volume as well as for estimating other tree measurement characteristics. The Schumacher and Hall (S&H) method yielded results similar to those of the ANN; however, the existing dependency between DBH and total height (H) could lead to multicollinearity issues, making the use of ANN potentially preferable. The choice between the two neural networks depends on the availability of tree age, as ANN2 requires only DBH and H for estimation. The results are not significantly different from those obtained with other traditional estimation methods; nevertheless, the use of linear and conventional models cannot be categorically dismissed. ANN can model complex, nonlinear relationships between variables and volume, making their implementation a potential improvement for forest management.